FreeLLMAPI
Use it at freellmapi.co ↗One request in. The best available model out.
FreeLLMAPI turns the scattered free tiers of the LLM ecosystem into one self-hosted, OpenAI-compatible API: 605 free models from 34 providers behind a single /v1 address.
It routes every request to the best model and key that still has room, and it runs on your machine, not as a hosted middleman.
The challenge
Free inference was everywhere. Usability wasn’t.
The major labs all offer free capacity. Each allowance is small, with its own SDK, model names, quota rules and failure modes. Together they’re serious compute, if something tracks it all.
The solution
Infrastructure you can actually see.
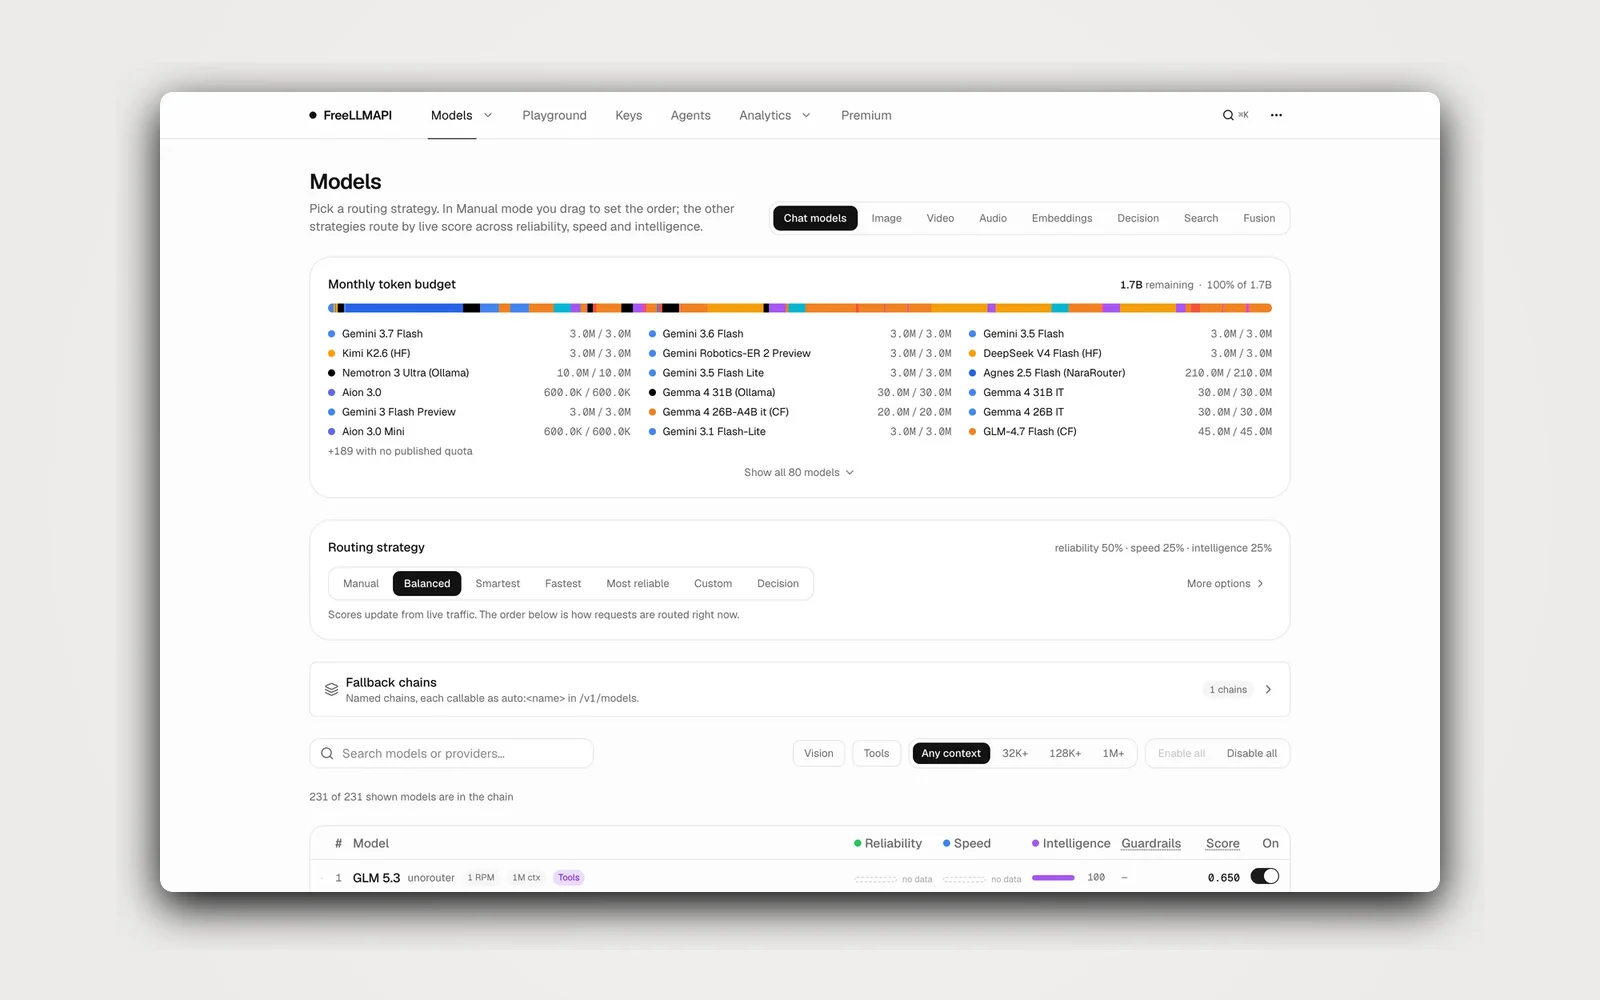
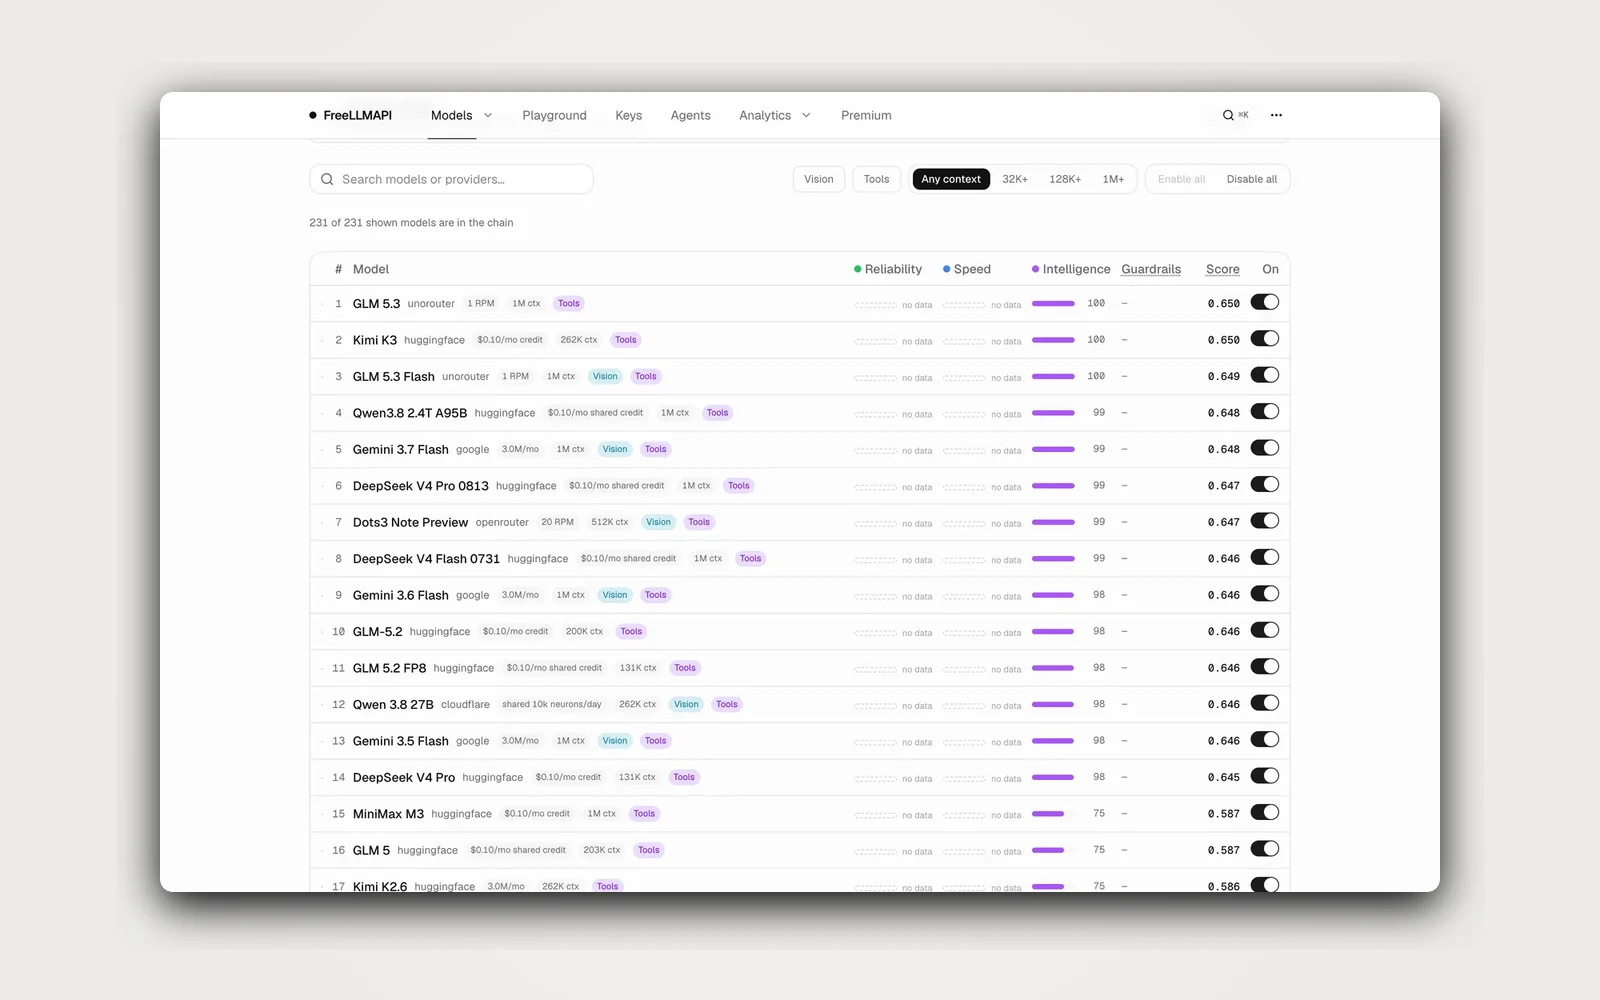
Each model is scored on capability, speed, reliability and remaining quota. On a rate limit, timeout or failure the key cools down and the request moves to the next route. An existing OpenAI client changes two values: base URL and key.
Keys stay in your own SQLite, encrypted with AES-256-GCM. It runs as a Docker service or a desktop app on macOS and Windows, in six languages.
[Demo] — FreeLLMAPI
- 01 / 04
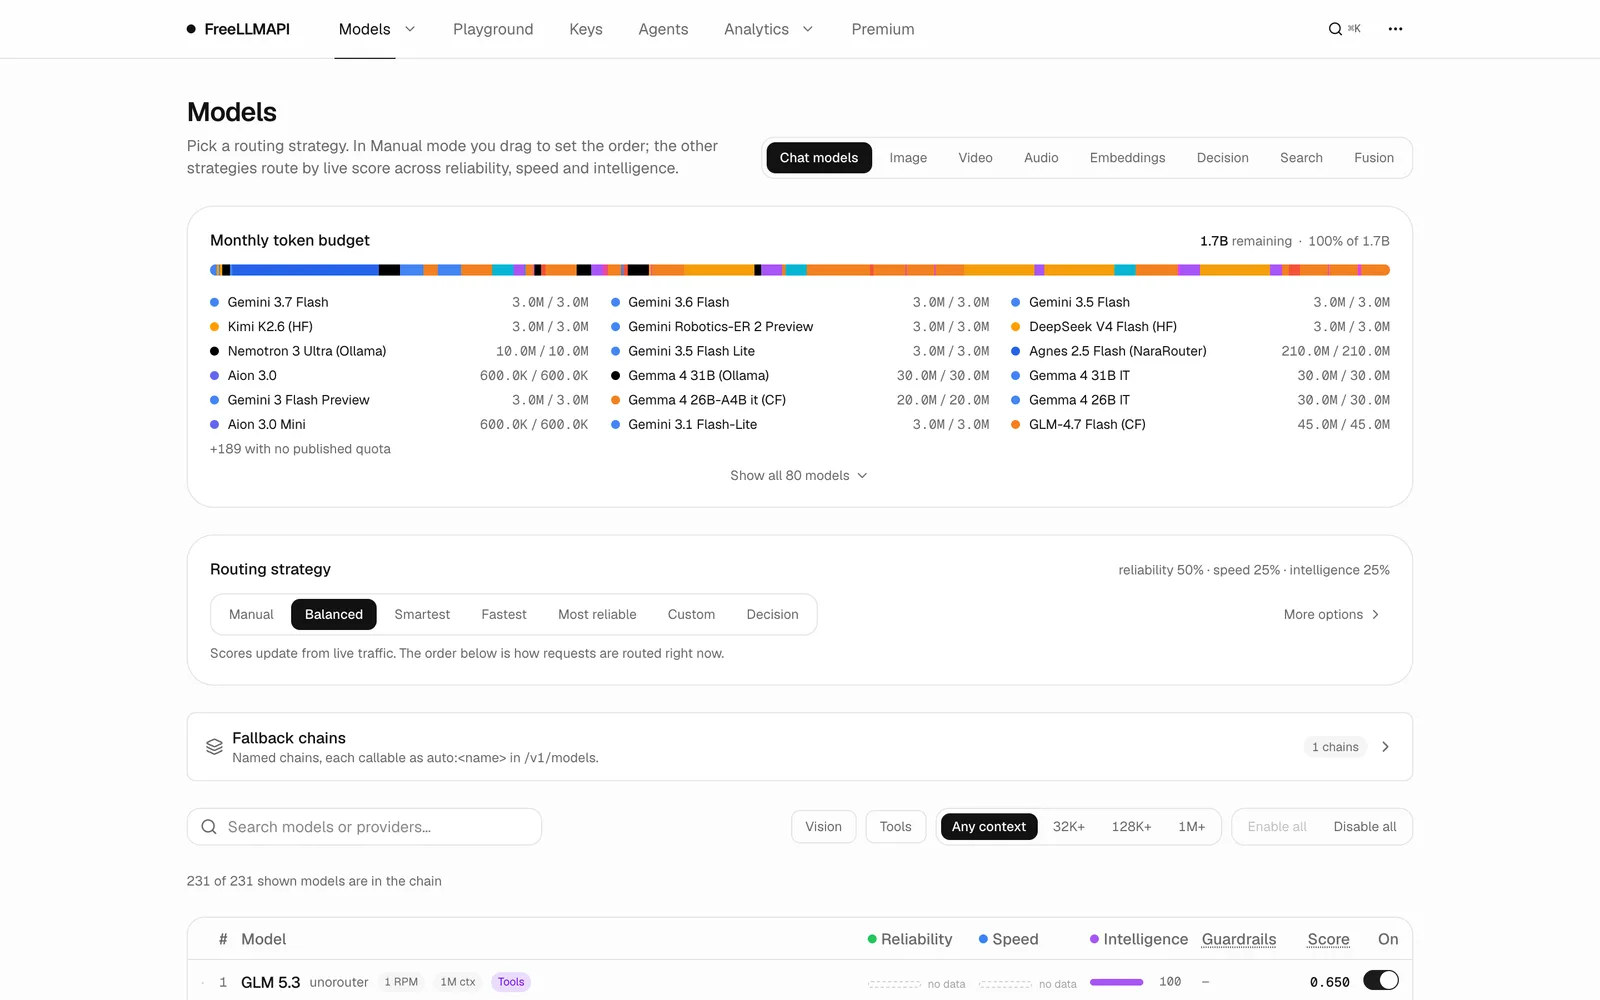
See your free capacity
The Models page starts with your monthly token budget: every connected provider’s free allowance, one segment per model.
- 02 / 04
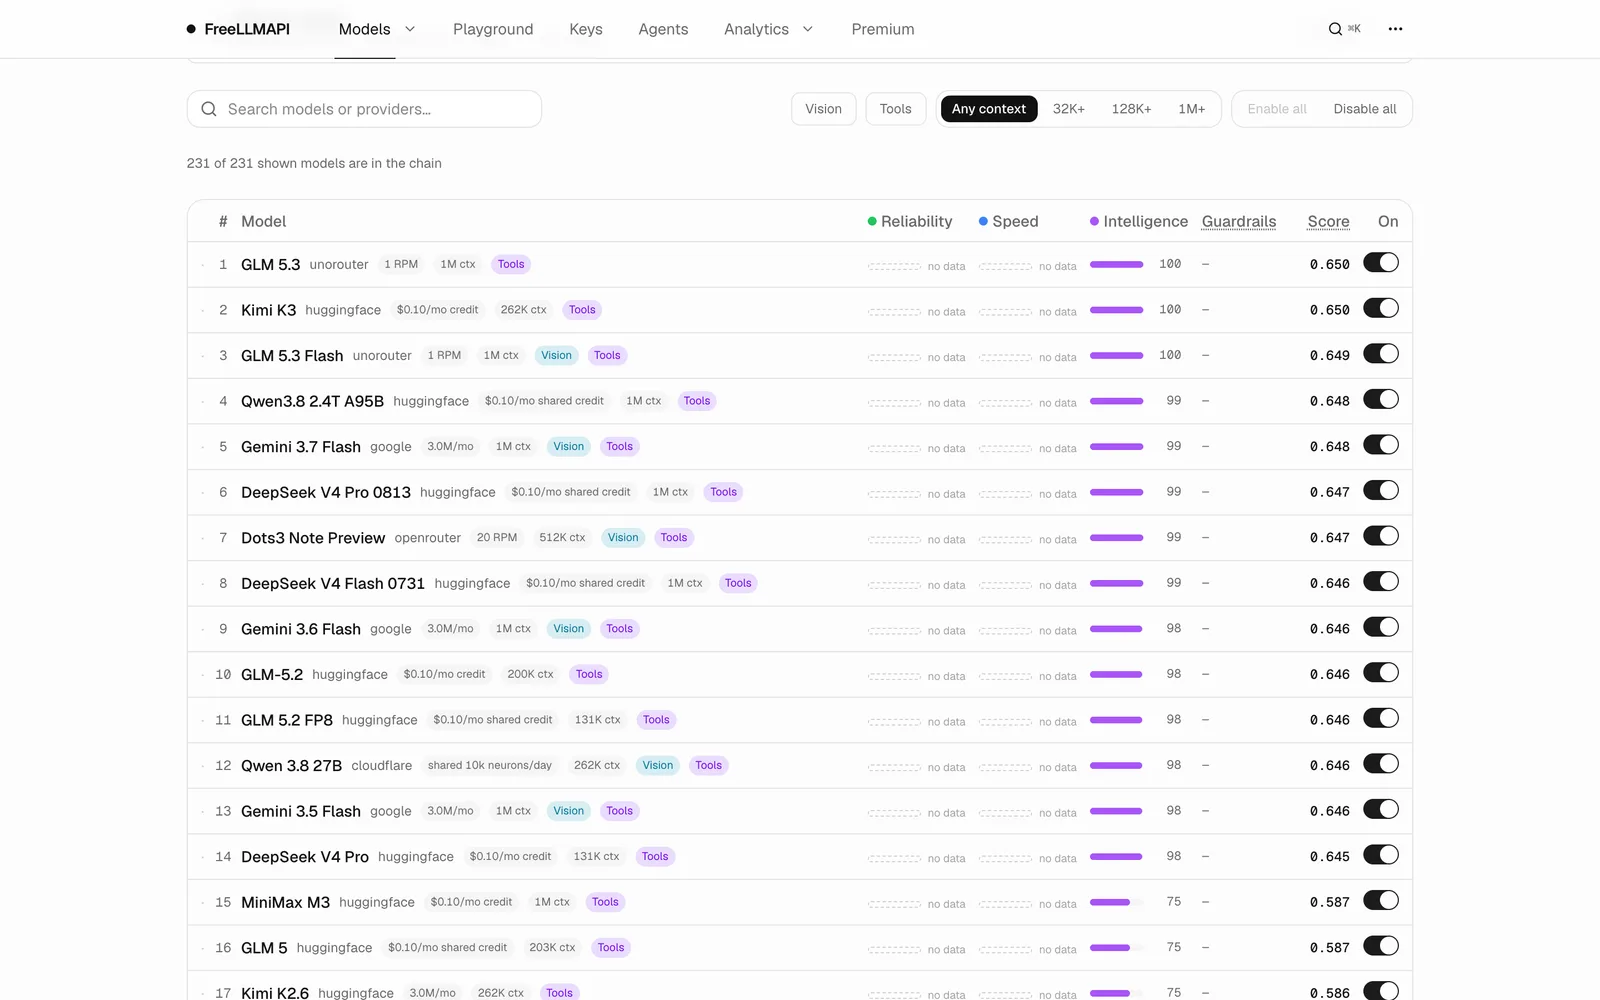
Choose how requests are routed
Balanced, Smartest, Fastest, Most reliable or your own order. Each model is scored from live traffic.
- 03 / 04
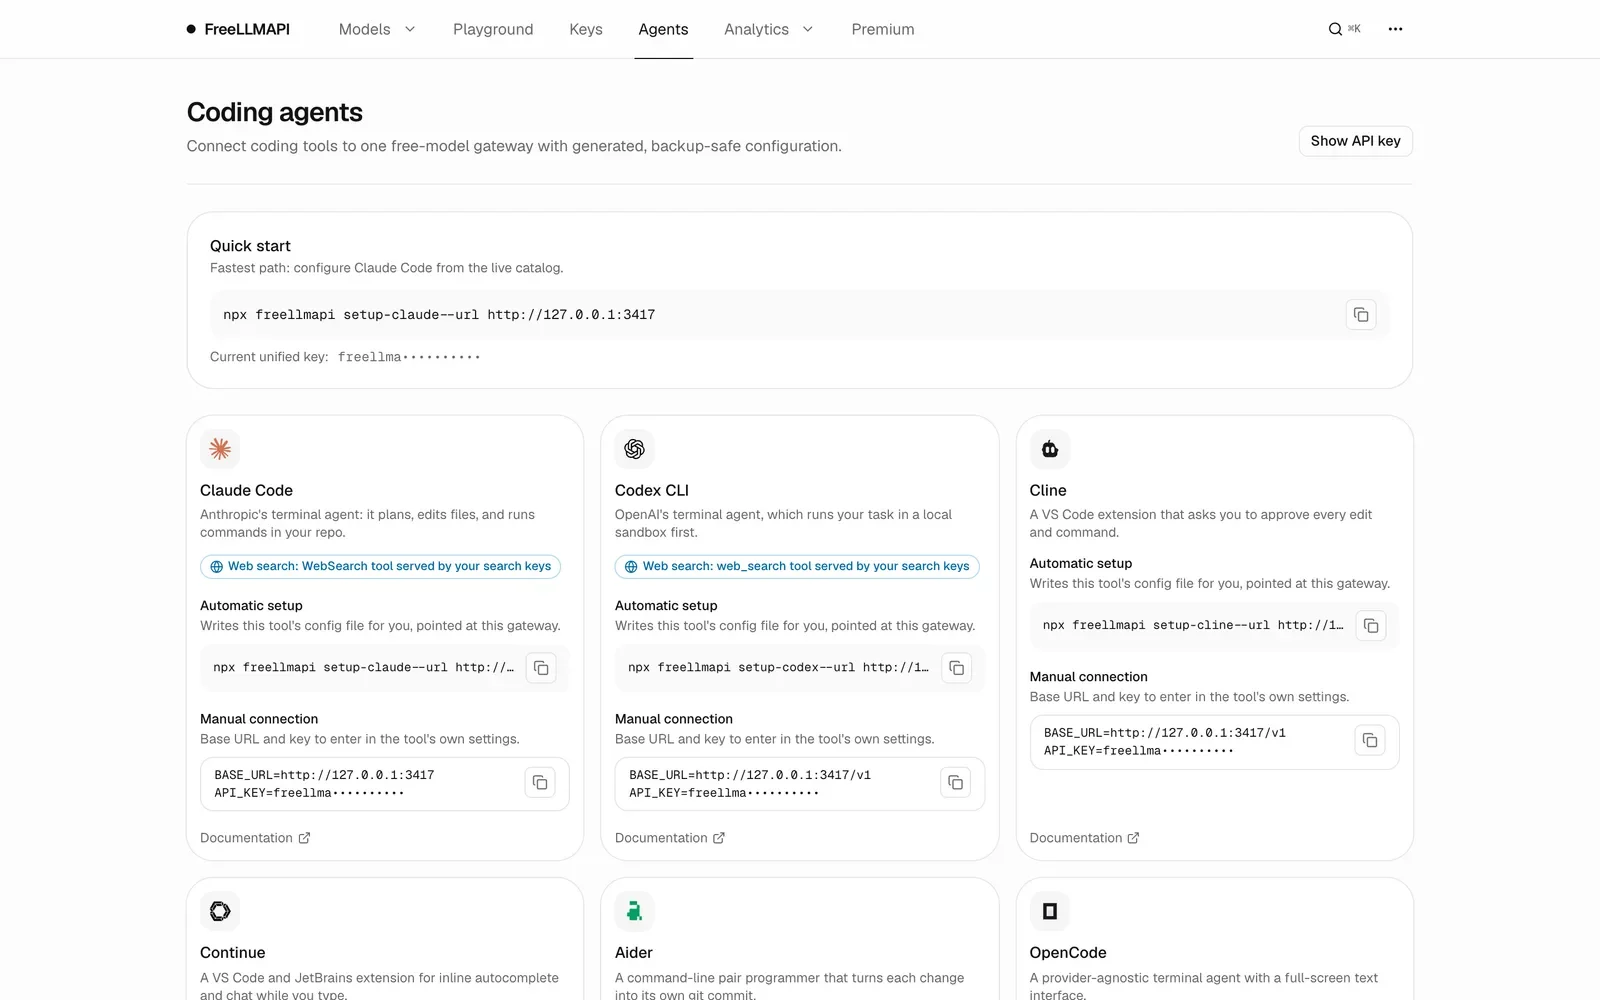
Connect your coding agents
One command writes the config for Claude Code, Codex CLI, Cline, Aider, OpenCode and more.
- 04 / 04
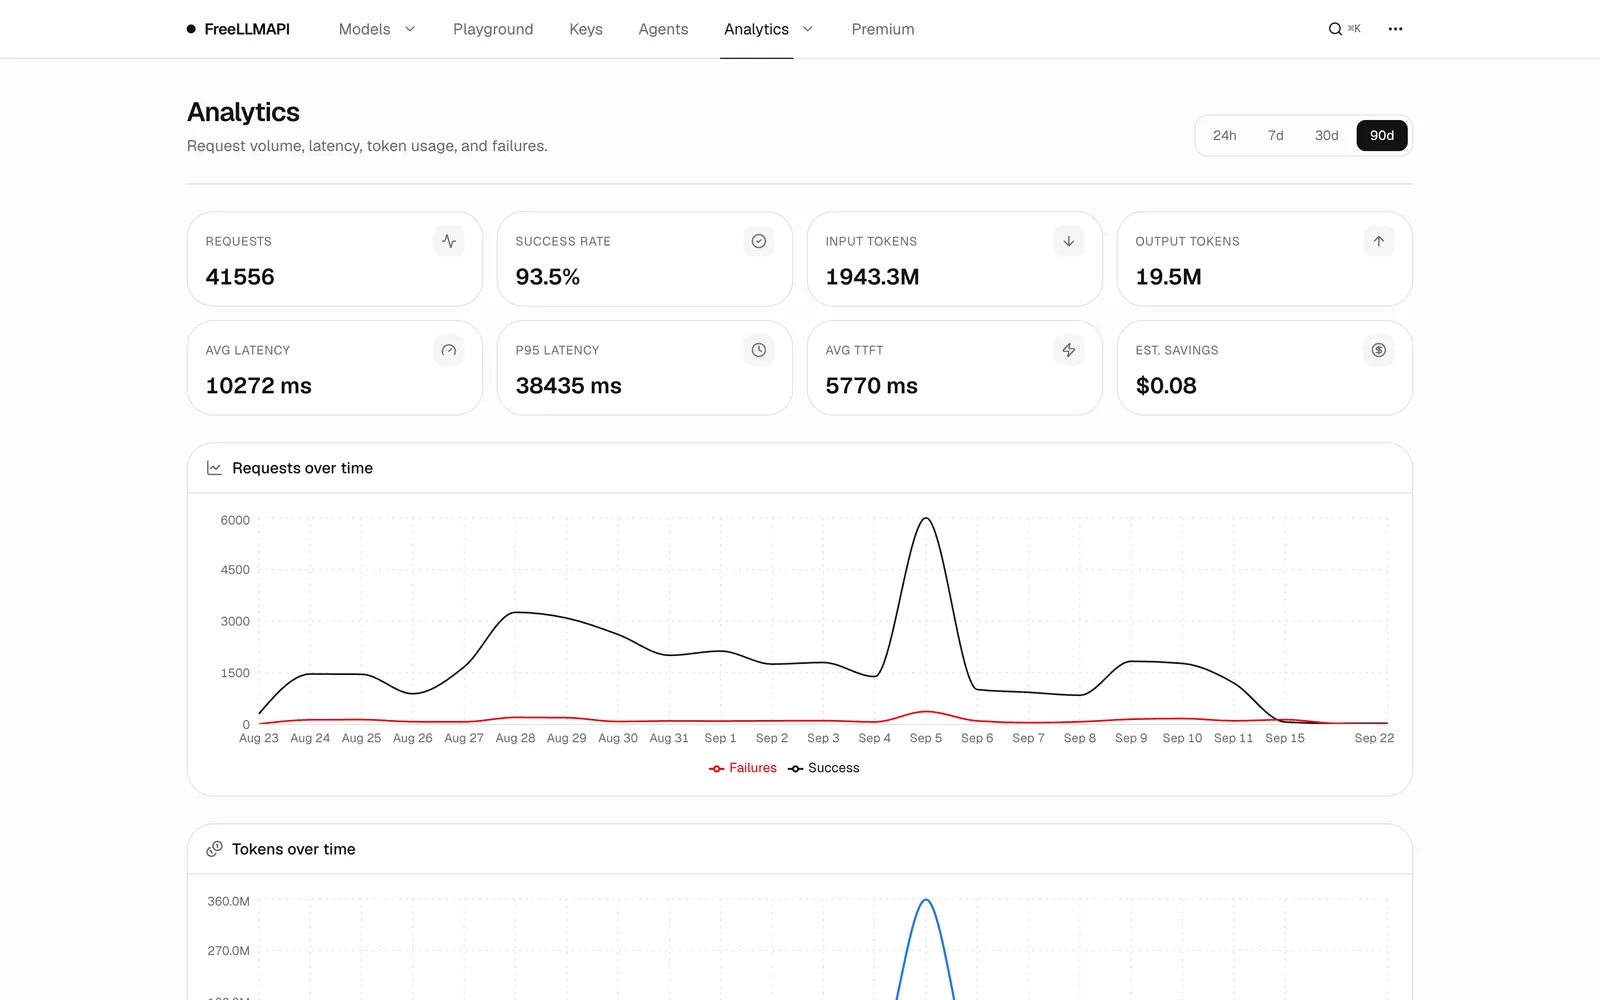
Watch your traffic
Requests, success rate, latency and token use, from the last 24 hours to 90 days.
The results
Want results like this?
Free models
Providers in one pool
Free tokens a month
 [Keep scrolling to see more]Next caseTutor operations agent